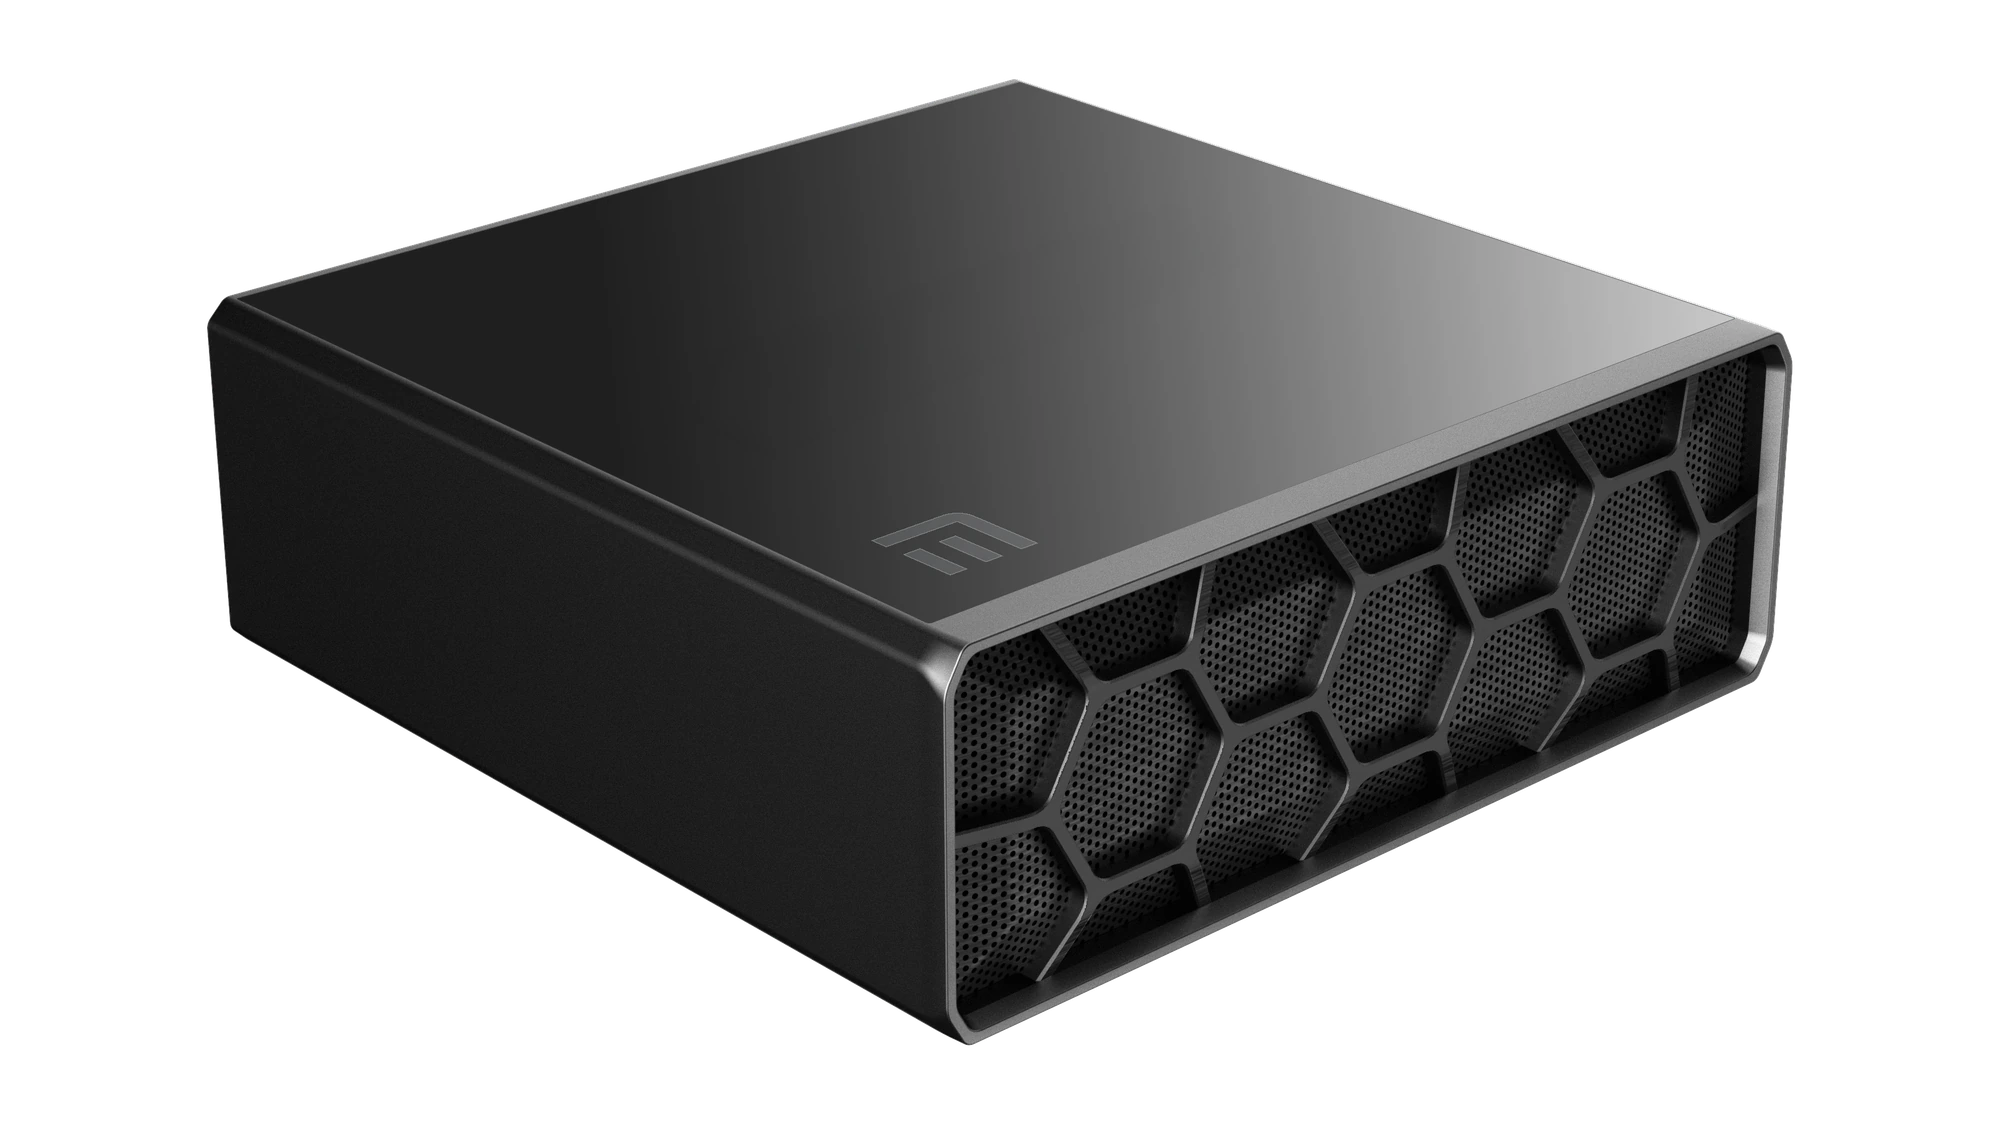
One AI petaflop, 128 GB of memory and your agents. All in a case shorter than a Rubik's Cube.
An assistant advises. An agent works.
UniStudio is the agent workshop that comes with your M.RED Hive. You give it a task, it opens the files, searches, writes and acts in your tools. It asks for your approval before any risky move.
- from install to first model
- 1 click
- ready-to-use agent roles
- 98
- model providers, local or online
- 24
Getting started
Install in one click
UniStudio checks memory and disk space, installs the model engine and downloads the models suited to your machine.
Give it your documents
PDF, Word, Excel: it indexes them locally and cites the source of every answer.
Set the limits
Four levels, from a simple action plan to fully automatic. Deleting a file or sending an email always requires your approval.
Agents that act
Read and write files, search the Web, launch a program, schedule a repeating task.
Four levels of autonomy
You choose how far it goes on its own.
- Ask every time
- Plan only
- Approve changes
- Automatic
Your documents, with their sources
A private knowledge base: every answer points to the passage it comes from.
Plugged into your tools
Through the MCP protocol, it works in the services you already use.
- Gmail
- Calendar
- Drive
- Notion
- GitHub
It works while you're away
Scheduled tasks run on their own. Anything needing your decision waits in the inbox.
The machine under control
Processor, GPU and memory in real time, with performance and fan modes.
Your AI moves forward while you sleep.
- 09:00
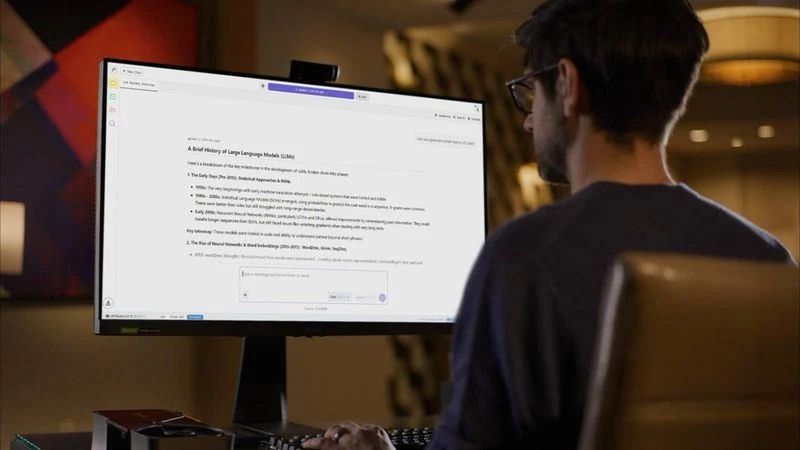
You arrive, it has already worked.
Your agent has sorted the inbox, filed yesterday's documents and prepared the status of your ongoing projects.
Agent · emails and files - 14:00
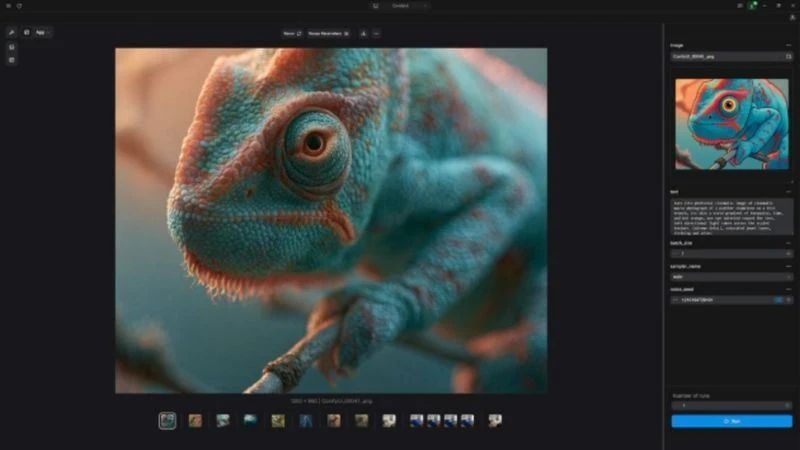
You create, it computes alongside.
Batch image generation, 4K video previews, 3D rendering in the background: with no cloud queue.
Creation · images and video - 19:00
You leave, it takes over.
It indexes your documents so they can be queried tomorrow, or starts a long video generation.
Scheduled tasks - 03:00
You sleep, it keeps watch.
140 W at most for the chip, silently. Anything needing your approval waits for you in the UniStudio inbox.
Idle · 140 W at most
Shorter than a Rubik’s Cube.
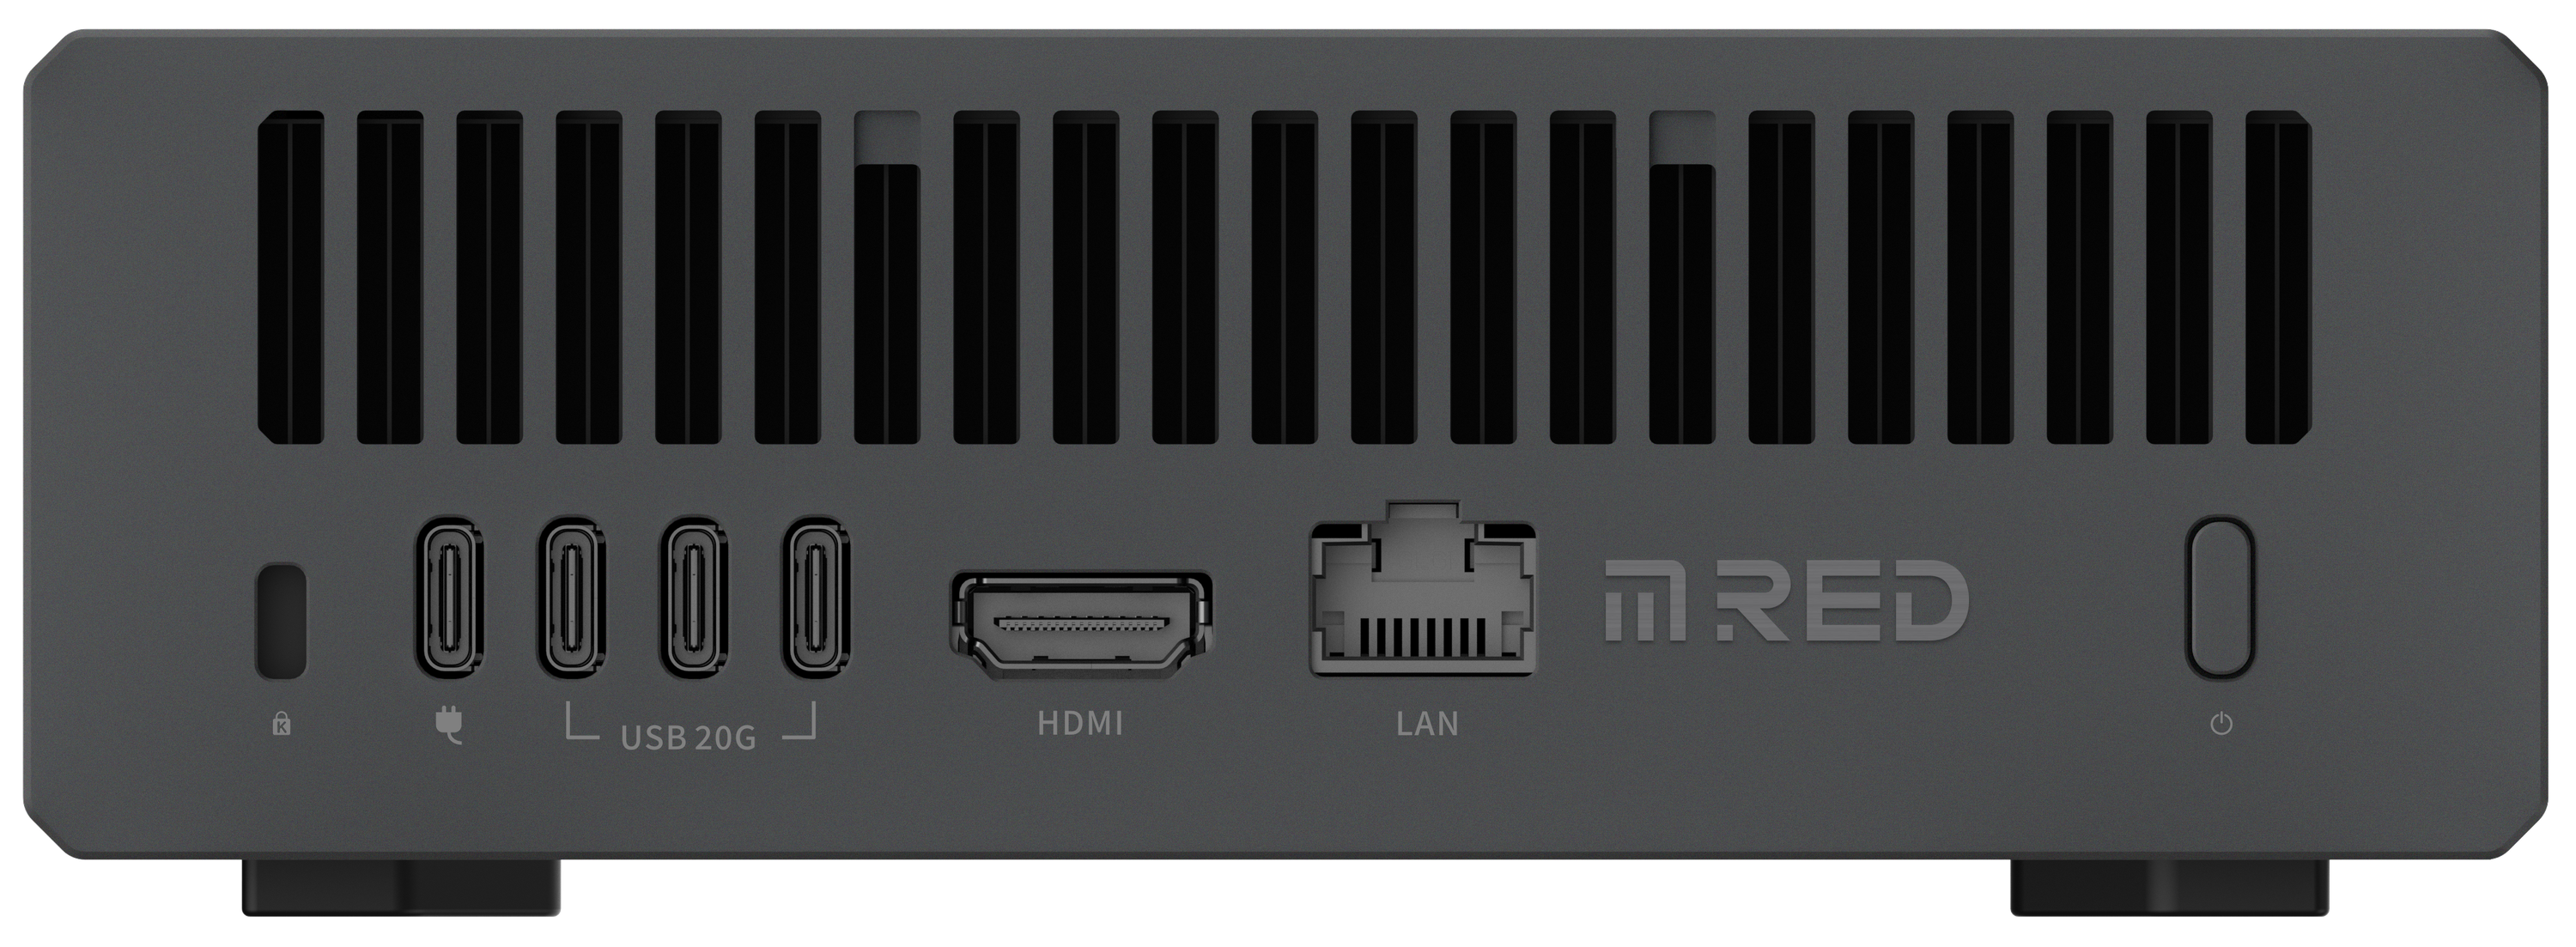
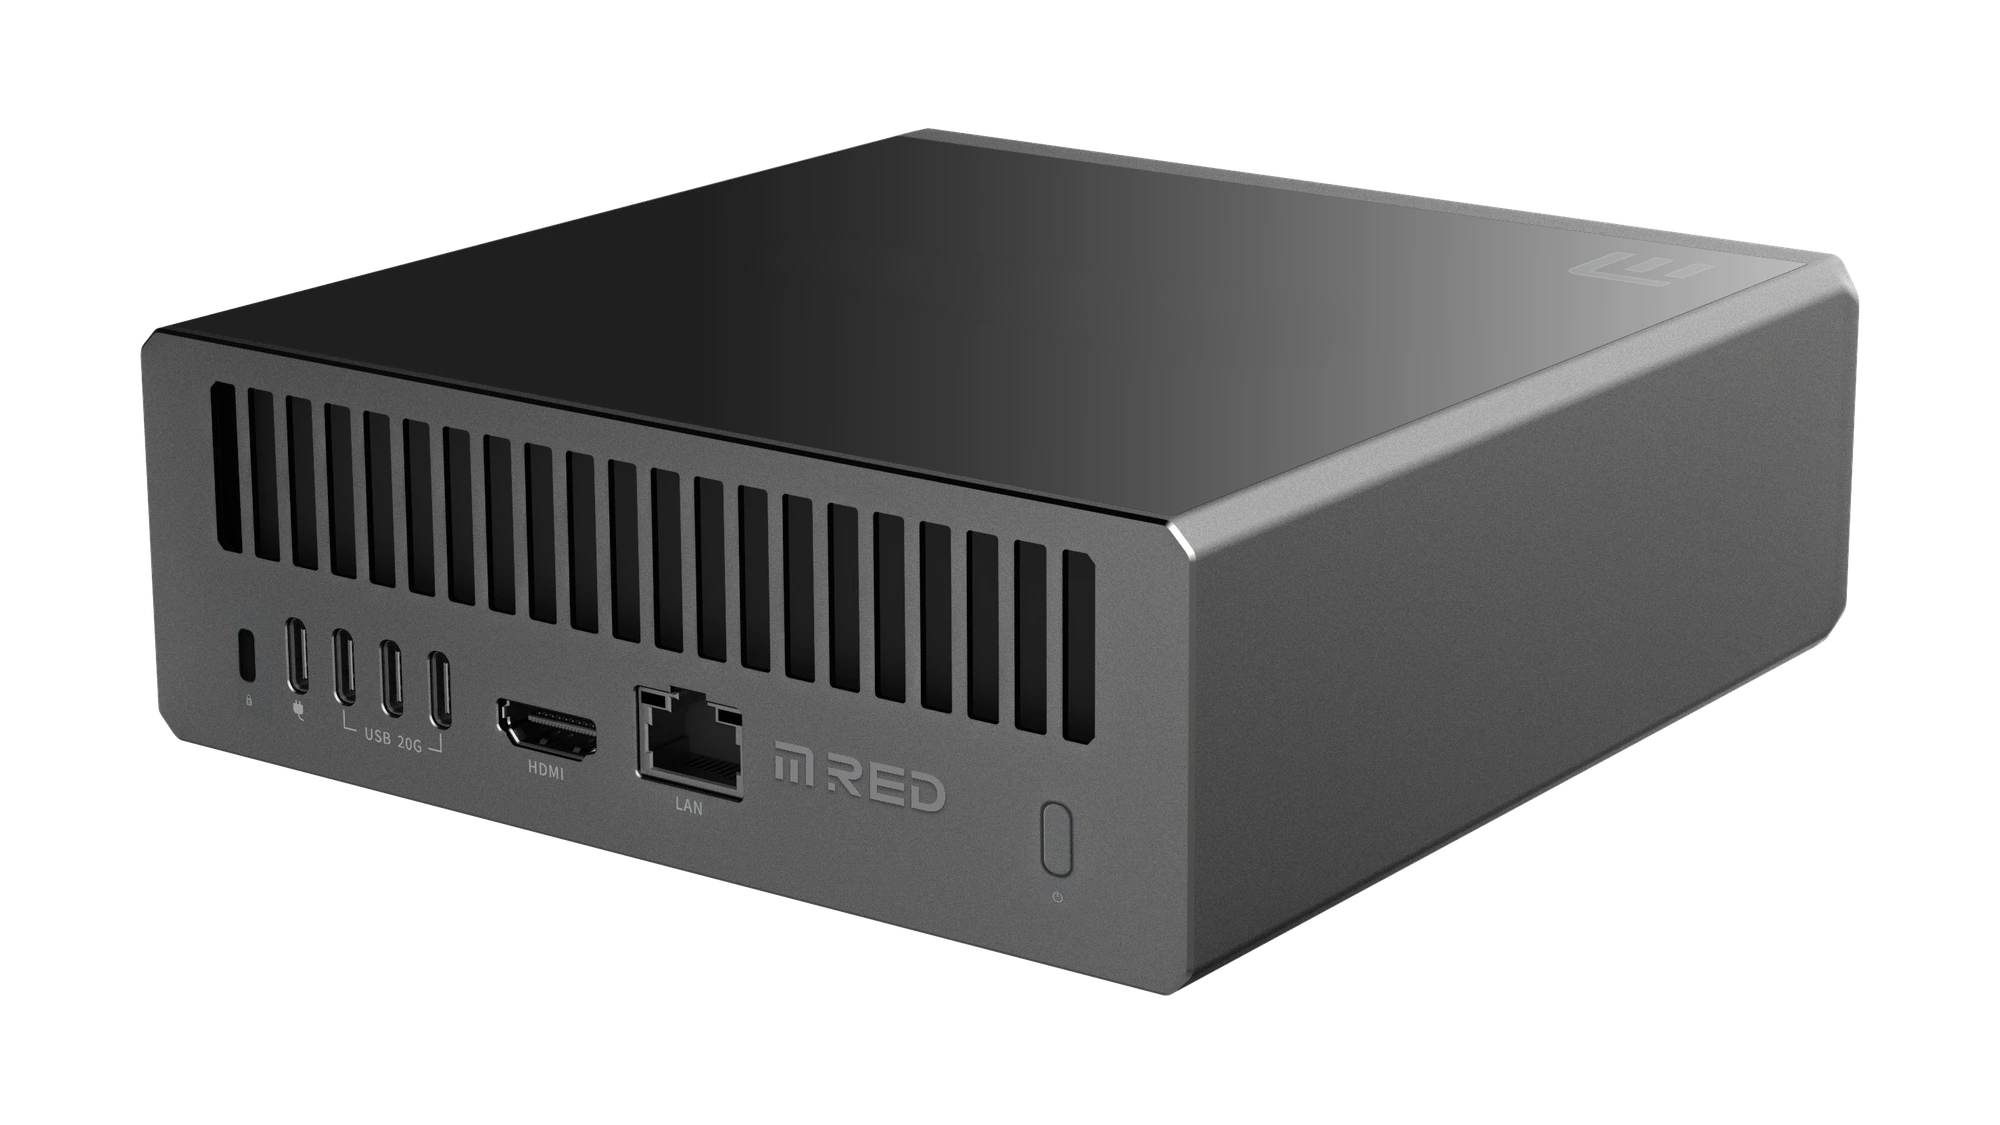
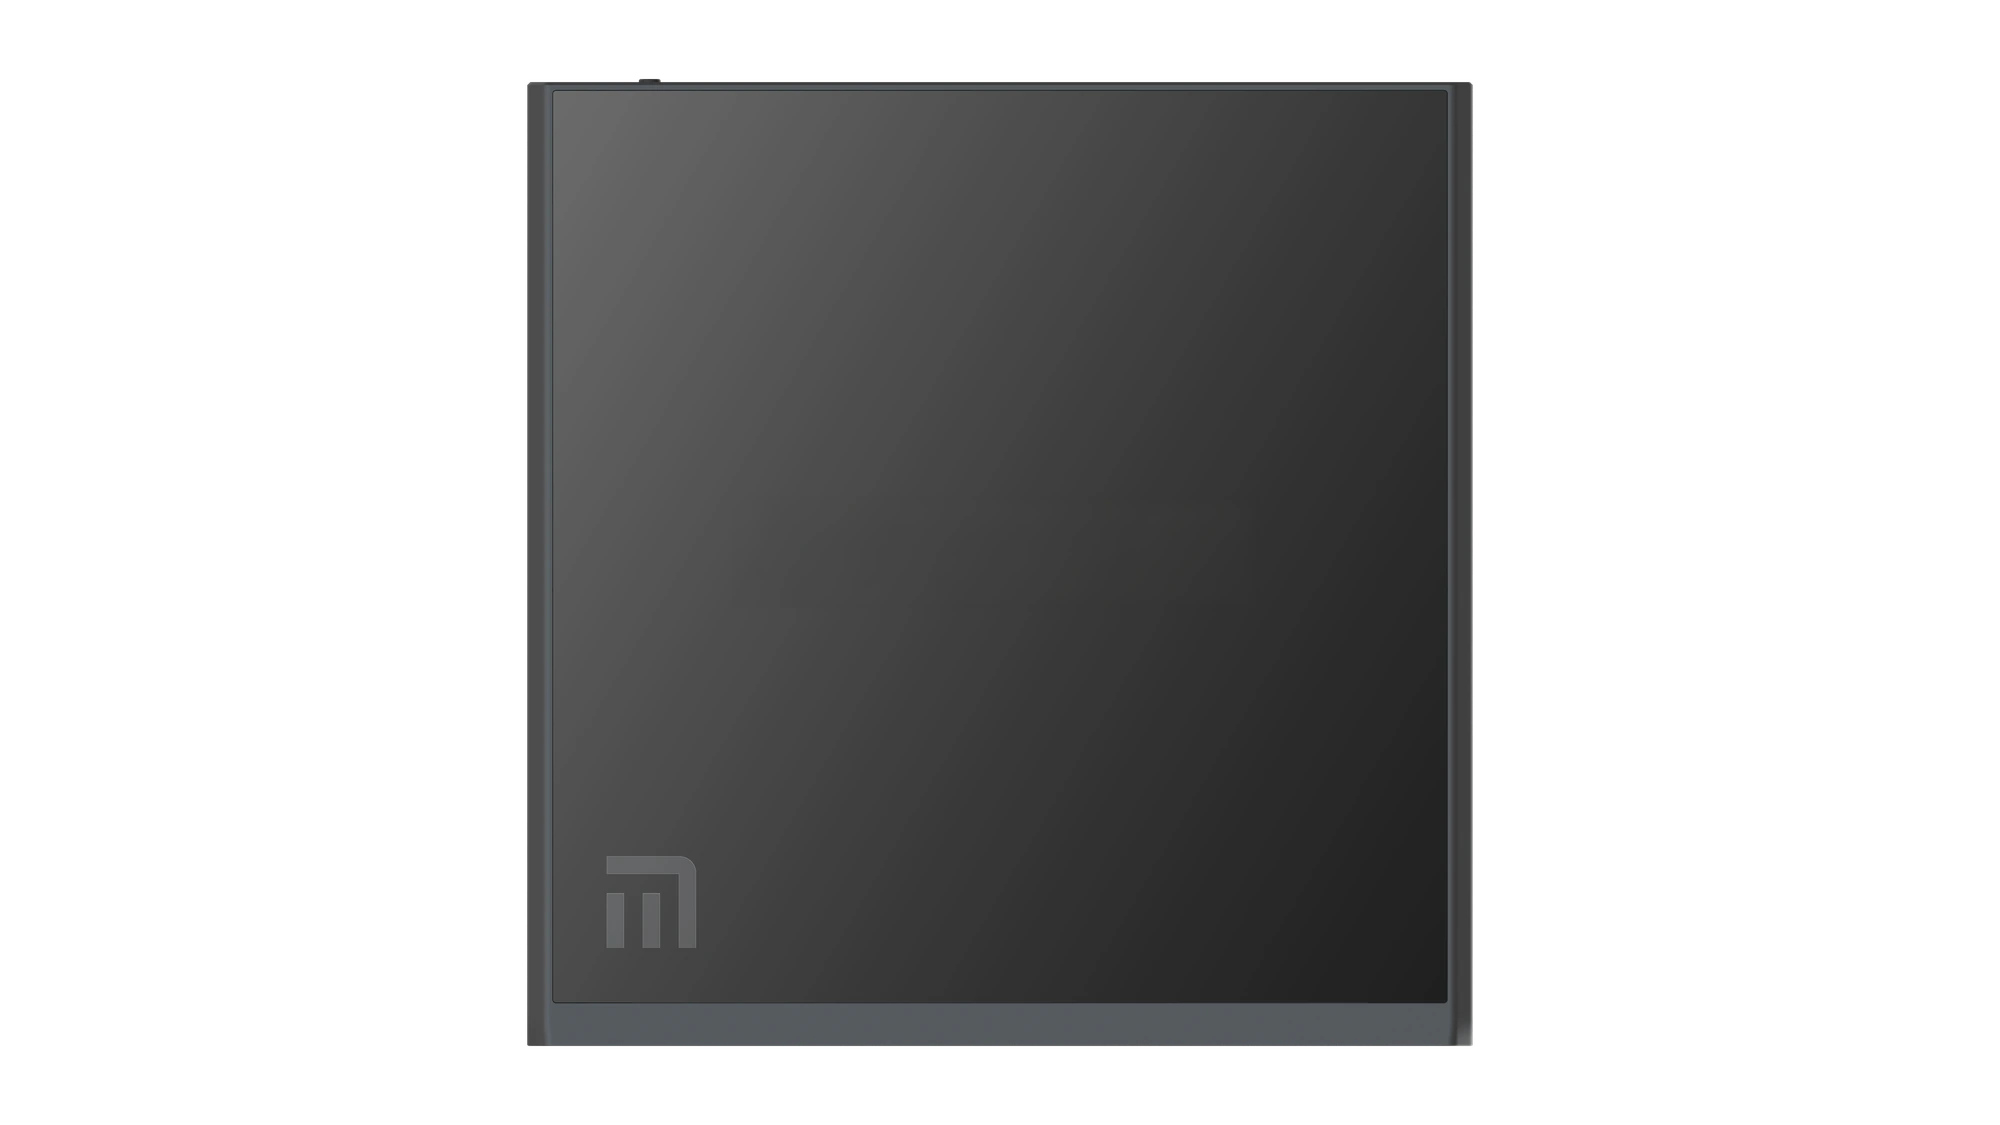
15.5 cm square, 5.1 cm high, 1.42 kg. Aluminium covers, anti-smudge treated glass top, and a metal mesh front with a honeycomb pattern that gave the range its name. All the connectors are at the rear.
A classic gaming tower takes up about thirty times more space.
Configure your M.RED Hive.
Four choices. Memory is decided at purchase: it is soldered to the chip.
Everything, in detail.
- ProcessorNVIDIA Grace, 20 Arm cores
- GraphicsNVIDIA Blackwell RTX, 6,144 CUDA cores
- AI performance1 petaflop at FP4 (1)
- Memory64 or 128 GB unified LPDDR5X9,400 MT/s, soldered
- Power140 W for the chip
- SystemWindows 11 (version 26H1)
- SecurityDedicated TPM chip, Nano slot
- Storage1 × M.2 2280 NVMe PCIe x4 slot
- Network10 GbE Ethernet, Wi-Fi 7 and Bluetooth
- Video outputs1 × HDMI 2.1b, 3 × USB-C DisplayPort 1.4a
- Power240 W USB-C power adapter, 100 to 240 V
- Dimensions155 × 158 × 51 mm
- Weight1.42 kg
- MaterialsAluminium, metal mesh, anti-smudge glass
Sources: NVIDIA RTX Spark specifications (desktop version) and manufacturer datasheet.
- AI performance AI performanceA thousand million million operations per second in FP4 (1): at home, what used to take a server.
- 1 petaflop
- Unified memory Unified memoryA single pool shared by the processor and the graphics. Large models fit in it whole.
- 128 GB
- Processor ProcessorNVIDIA Grace, an Arm architecture from the data centre.
- 20 cores
- Graphics GraphicsCUDA Blackwell, with 5th-generation Tensor Cores and 4th-generation RT Cores.
- 6,144 cores
- Power draw Power drawFor the chip, at most: less than a single high-end gaming graphics card.
- 140 W
- Local models Local modelsParameters at most, with 128 GB: models the size of those behind online services, on your desk (2).
- 200 bn
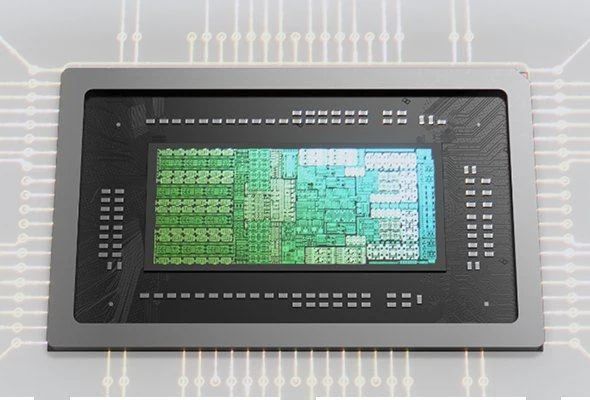
Two brains, one chip.
In a conventional PC, the processor and the graphics card talk to each other through the motherboard. RTX Spark brings them together on the same chip, with the same memory.
More memory, bigger models.
An AI model is measured in billions of parameters. The more it has, the finer its reasoning, and the more memory it needs. Choose a size to see what it allows.
24GB32GB48GB64GB128GB
- Local model, maximum
- 12 billion parameters25 billion parameters60 billion parameters90 billion parameters200 billion parameters
- Agents
- In the cloudIn the cloudLocallyLocallyAdvanced, locally
- 3D scene
- InteractiveInteractiveInteractiveUp to 45 GBUp to 90 GB
NVIDIA benchmarks for quantised models (2). Memory is shared with Windows and your applications. The Hive range comes in Hive 64 and Hive 128.
8B
Everyday chatQuestions, rewording, quick translation.
32B
Write and summariseReports, summaries of long documents.
70B
Code and analyseDevelopment assistant, data analysis.
120B
Reason like cutting-edge modelsUp to one million context tokens: a whole case file read in one go (3).
200B
Several agents in parallelThe largest model while other agents are working.
Orders of magnitude. Actual capacity depends on quantisation and context length.
The same AI, at two addresses.
| AI in the cloud | Tech specs | M.RED Hive |
|---|---|---|
| Every question travels across the Internet and waits its turn. | Response | Immediate, without depending on the network. |
| Your documents go off to third-party servers. | Privacy | Nothing leaves: your data stays in the room. |
| A subscription per person, sometimes a price per question. | Cost | One purchase, and no cost per request. |
| The model changes when the provider decides. | Control | You choose the model and when to change it. |
| Network outage, no more assistant. | Offline | It keeps going, even without a connection. |
UniStudio can also draw on an online model when you choose: the decision is yours.
What local AI changes in your day.
Images, lighting, camera angles: try, keep, start again, with no queue.
Concept exploration
Hand sketches or a cloud queue: long seconds, sometimes minutes per image.
Images appear as the idea unfolds. Relight a scene or change a background, with no limit on attempts.
Video editing
One more angle or one more effect meant frame-by-frame touch-ups or a long render.
Angles and effects layer up in 4K preview. Camera 4:2:2 is decoded by the hardware.
Compare, compress, measure: on the machine, with no quota.
Parallel tuning
Cloud quotas meant one tuning run at a time, across several sessions.
Several versions run together, metrics side by side. Overfitting shows up straight away.
Model quantisation
Every compression attempt meant sending the model back to measure the loss.
From FP16 to INT4 on site: the right balance between speed and accuracy is found fast.
Documents of every kind, reconciled locally.
Account reconciliation
ERP, stock and bank statements compared line by line: misfilings, duplicate payments.
AI reads the documents, matches the systems and isolates every discrepancy.
Stress testing
Exchange rates, raw materials and late payments all at once: the spreadsheet gives up.
Simulations run on historical data produce a report ready for management.
Contracts go through no third-party server.
Contract review
An ambiguous clause or a missing liability cap takes hours of a trained eye.
Fine-grained comparison flags risky clauses and contradictions.
Hearing preparation
Anticipating the other side's arguments rested on the partners' experience.
Simulations based on case law get the whole team ready.
Health data stays on site.
Imaging
Reviewing CT and MRI scans took half a day per report, with the eye strain that comes with it.
Assisted comparison and 3D reconstruction during the consultation, supporting the doctor.
Drug interactions
Leaflets were checked one by one; rare combinations slipped through.
History is cross-checked against the diagnosis, an alert appears at prescription.
A purchase, not a subscription per seat.
Cross-department analysis
ERP, CRM and logistics consolidated by each department, with results arriving late.
Sources are brought together on site, bottlenecks show up straight away.
Searching your archives
Years of proceedings and projects scattered about, too sensitive for the cloud.
An offline search that answers by citing your own documents.
Illustrative scenarios. Medical and legal uses remain the professional's responsibility.
Your software, RTX-accelerated.
An Arm processor running Windows 11
Arm applications and the CUDA stack run natively. x86 software goes through Windows emulation: check your business software and your device drivers before buying.
What is an AI agent, in practice?
An assistant answers. An agent acts: you give it a goal ("prepare Monday's update from my emails"), it breaks the task down, opens the files it needs, uses your tools and hands you the result. With UniStudio, it asks for your approval before any risky move.
Will my software run on this PC?
Windows 11, Arm applications and the CUDA stack run natively. x86 software goes through the emulation built into Windows. Some older utilities, business software or device drivers may not work: list them before buying, and our support team will help you check.
64 or 128 GB?
64 GB is enough for a permanent agent and models up to 90 billion parameters. 128 GB opens up cutting-edge models and several agents at once. The memory is soldered: you choose it at purchase.
How does it compare with a PC fitted with an RTX 5090?
An RTX 5090 tower has more raw power for gaming and rendering, with 32 GB of graphics memory. The RTX Spark SFF shares up to 128 GB between the processor and the GPU: it fits far larger AI models, in a chassis around thirty times smaller than a gaming tower, and 140 W for the chip.
What about NVIDIA's DGX Spark?
DGX Spark runs on Linux (DGX OS) and targets developers who train and fine-tune models. The M.RED Hive runs on Windows 11: it keeps your creative software, your games and your office tools.
Is it noisy?
The chip is capped at 140 W, which allows for compact, discreet cooling. UniStudio offers fan modes, from silent to turbo.
Do you need an Internet connection?
For setup and downloading the models, yes. After that, local models and your documents work offline.
Notes
(1) FP4 AI performance with sparsity, according to NVIDIA, (2) model size guidance by memory capacity: NVIDIA "Help me choose" page (quantised models), (3) models up to 120 billion parameters with a one-million-token context, according to NVIDIA, (4) depending on the display and cable used, (5) NVIDIA CUDA 12.1, TensorRT and NVFP4 supported, according to the NVIDIA RTX Spark specifications, (6) according to the NVIDIA "Help me choose" page (performance varies by game and settings).
Sources. NVIDIA RTX Spark N1X specifications (desktop version) and manufacturer datasheet, November 2026. NVIDIA, RTX, GeForce, CUDA, DLSS, G-SYNC and Blackwell are trademarks of NVIDIA Corporation. NVIDIA visuals used with permission. The amounts shown by the configurator are given as examples.